Problem and Constraints
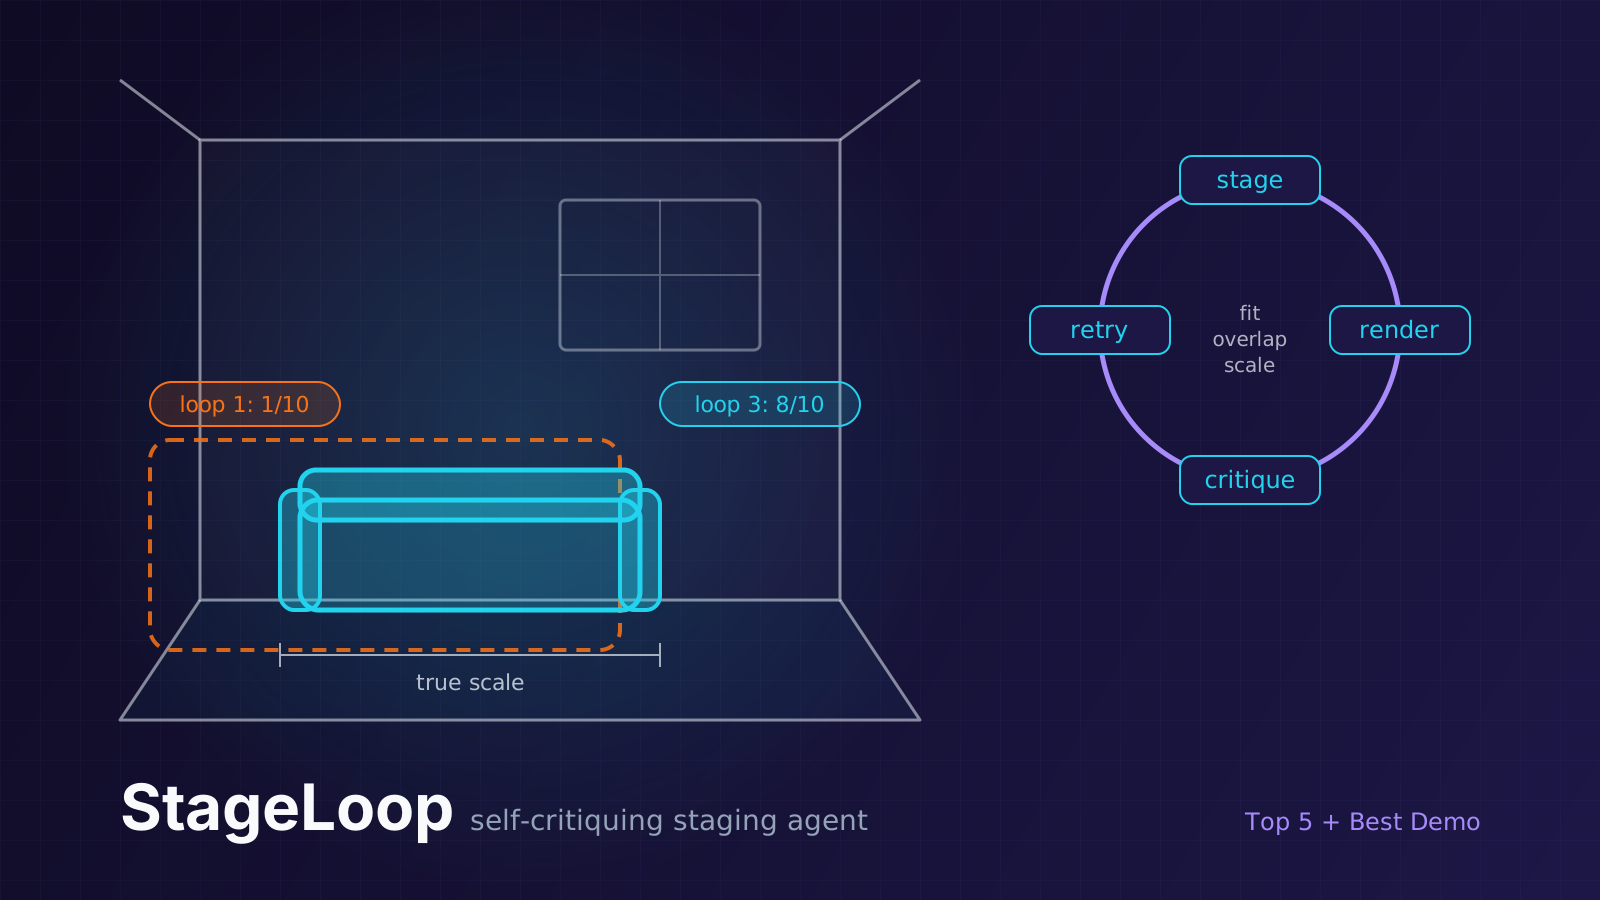
Single-shot image generation for virtual staging produces furniture at the wrong scale or overlapping walls, with no mechanism to notice or fix it.
- One-day solo build, so the loop had to be simple, observable, and demo-stable.
- Listing data had to be fetched and paid for automatically on every scrape.
- Inference and hosting had to stay cheap enough to run continuously.
My Approach
Considered: I considered a single generation pass with a carefully tuned prompt.
Chose: I chose a plan, render, critique, retry loop that scores each render and feeds the critique back in.
Rejected: I rejected single-shot generation because it has no way to detect its own scale and overlap errors.
Considered: I considered a free-form model judgment of whether a render looked good.
Chose: I chose explicit scores for fit, overlap, and scale so each loop had a measurable target.
Rejected: I rejected vague self-assessment because it does not converge and cannot be shown in a demo.
Considered: I considered scraping listing data manually ahead of the demo.
Chose: I chose automated per-scrape purchases through x402 and normalization through a live Nexla pipeline.
Rejected: I rejected pre-scraped static data because the agent needed to work on live listings.
System Design
Loading diagram…
Listing data is purchased per scrape through x402 and normalized in a live Nexla pipeline. Placement and self-critique inference run on AkashML; each render is scored for fit, overlap, and scale, and failing scores drive another placement pass.
Implementation Highlights
- Plan, render, critique, retry loop with explicit fit, overlap, and scale scoring.
- Automated per-scrape listing-data purchases through x402.
- Live Nexla pipeline that normalizes listing data before placement.
- Placement and self-critique inference on AkashML, deployed for about $1.73 per month.
Tech Stack
Outcomes
- Top 5 and Best Demo at Loop Engineering Hackathon SF.
- Render score improved from 1/10 to 8/10 over three loops.
- Deployed for about $1.73 per month.
Retrospective
Problem: Agents improve only when the critique is concrete enough to act on.
What I tried: I replaced open-ended self-review with numeric fit, overlap, and scale scores fed back into placement.
What I'd do differently: I would log every loop iteration from the start to tune stopping criteria with real data.